The ticket says: "Invoices are showing the wrong tax rate for EU customers." No stack trace, no reproduction steps, and a screenshot of a PDF.
Before you can fix that, you need to know when it started. Not out of curiosity. Whether this is a regression or a bug that has always been there changes what you do next, and if it is a regression, the commit that introduced it usually explains the cause faster than reading the code does.
There is a version of this workflow that involves git bisect and a version that
involves reading the history. Most people jump straight to the first. The second is often
faster, and it is what this post is about.
#The first fork: regression or latent bug
Ask one question before anything else. Did this ever work?
If it used to work, you have a regression, and the history contains the answer. There is a commit where the behaviour changed, and every technique below is aimed at finding it.
If it never worked, the history has nothing for you. Nobody broke this, it was always broken and nobody hit the specific combination of inputs before. Stop looking at Git and start reading the code path.
Distinguishing the two takes about two minutes. Check out a tag from a few months back, reproduce, and see. That is a much better use of the first two minutes than guessing.
git checkout v1.2.0
# reproduce
git checkout -    # back to where you were
#Tags are the coarsest and most useful boundary
If you tag releases, you already have checkpoints that map to what your users are running. That is the fastest way to cut the range.
# Releases, newest first.
git tag --sort=-creatordate | head -10

# Everything that shipped between two of them.
git log v1.4.0..v1.5.0 --oneline
Work backwards: reproduce on the current release, then the one before, then the one before that, until it stops reproducing. Two or three checkouts usually finds the boundary, and each one halves the remaining range in the same way bisect does, just at release granularity instead of commit granularity.
Once you know the bug is in v1.5.0 and not v1.4.0, the range is v1.4.0..v1.5.0. If
you release weekly, that is thirty or forty commits rather than two hundred.
Two flags make that list readable:
# Collapse feature branches into their merge commits.
git log v1.4.0..v1.5.0 --oneline --first-parent

# Only commits that touched the relevant code.
git log v1.4.0..v1.5.0 --oneline -- src/billing/
The second one is the highest-leverage command on this page. A tax calculation bug almost certainly came from a commit that touched the billing directory, and filtering by path routinely takes a forty-commit range down to three. If you are not fluent with the log flags, the git log tutorial covers the ones worth memorising.
#Searching for the change itself
Filtering by path narrows to a directory. Two flags narrow to the actual code.
# Commits where the number of occurrences of this string changed.
git log -S "requestTimeout" --oneline

# Commits whose diff contains a line matching this regex.
git log -G "vatRate\s*=" --oneline

# History of one function or line range, following it across renames.
git log -L :calculateVat:src/billing/vat.ts
-S is called the pickaxe and it answers "when did this string appear or disappear",
which is exactly the question you have when a constant changed or a call was removed. -G
is broader: any diff line matching the pattern, including ones that were only moved.
-L is the one people do not know exists and is often the fastest route to an answer. Give
it a function name and a file and it prints every commit that changed that function, with
the diff, in reverse chronological order. On a regression localised to one function, this
frequently ends the investigation in one command.
Add --all if the change might have arrived through a branch that was later deleted, and
--follow on a file that was renamed.
#Reading the graph rather than the list
A flat list of forty commits tells you what changed. It does not tell you how those changes arrived, and that shape is often the clue.
In a rendered commit graph you can see that of those forty commits, thirty came from three feature branches merged in the same week, and the other ten went straight onto the release branch. That is a different set of suspects than a flat list implies. A regression in tax rates is far more likely to come from the "rework the pricing engine" branch than from ten scattered commits, and you can see that at a glance rather than inferring it.
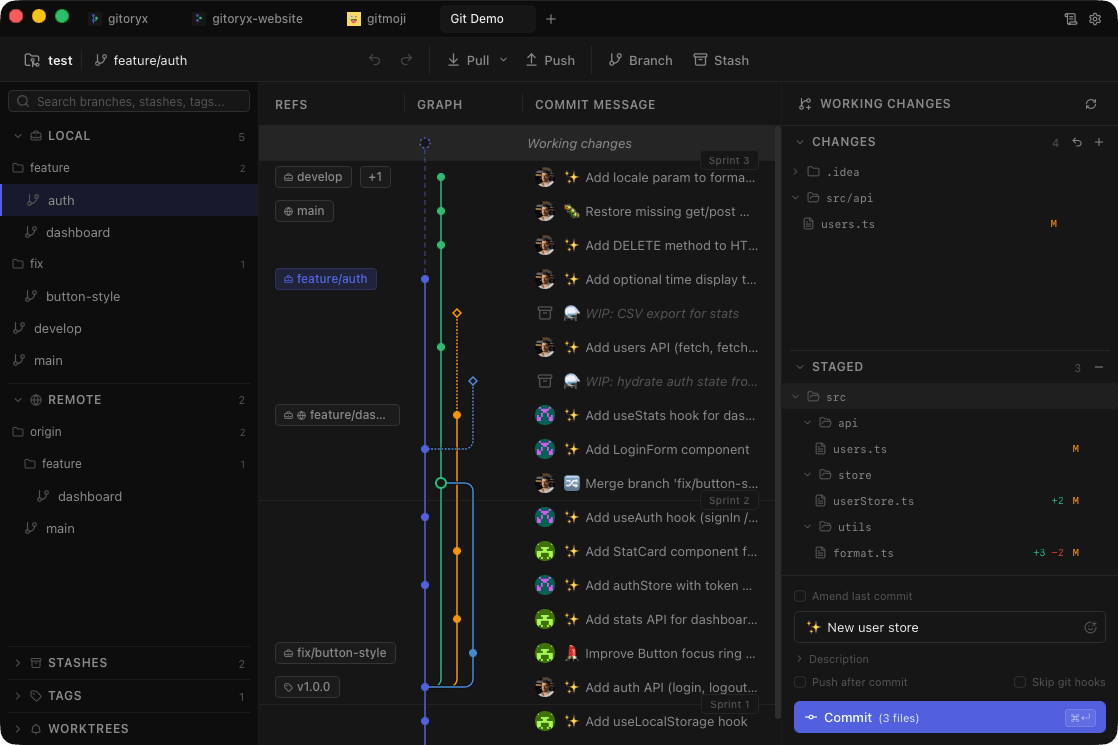
The specific things worth looking for:
Merge commits with big branches behind them. A single merge can bring in fifty commits. In a list it is one line. In a graph it is a visible lane.
Tags sitting inline. Seeing exactly which commits fall between two release markers removes the step where you compute a range and hope you got it right.
Commits that landed out of order. A cherry-pick or a late merge that put a change into a release after the branch was cut is a classic source of "but that was tested" bugs, and it is obvious in a graph and invisible in a list.
#When you do not tag every deploy
Plenty of teams ship continuously and have no meaningful tags. The range then has to come from time or from process boundaries.
Time is the crude version and it works:
git log --since="2026-08-15" --until="2026-09-01" --oneline -- src/billing/
If you deploy from CI, you can usually do better than dates. Whatever your pipeline records as the deployed revision is a commit SHA, and two of those bracket the incident exactly:
# Everything between the deploy that was fine and the one that was not.
git log --oneline 8f3a91c..4a91f3d -- src/billing/
Teams that do not tag releases almost always have this information somewhere: a deploys
table, a Slack channel where the bot posts, a /version endpoint that returns the build
SHA. It is worth finding out where, once, because it converts every future incident from a
date range into an exact commit range.
Sprint boundaries are the other option, and they line up with how the work was actually organised. A bug reported in the second week of Sprint 14, in a feature shipped during Sprint 13, gives you a range with an explanation attached: you know what the team was working on, who was on it, and what was rushed.
Gitoryx draws sprint boundaries directly in the commit graph. You configure a start date, a duration and a sprint number, and dividers appear in the history where each sprint began. Clicking a divider opens a popover with the commit count, how many people contributed, and every commit in that sprint in one list.
For triage that turns "sometime in the last month" into "these 22 commits, by these three people, during the sprint where we reworked pricing", which is a materially different starting point. The same view is what our changelog and sprint visualisation tutorial walks through if you want to see how it is set up.
#Reading the commits themselves
Once the range is down to twenty or thirty commits, do not automate yet. Read them.
This is the step people skip, and it is often the one that finishes the job. A tax rate
bug in a range containing ♻️ extract the VAT lookup into a shared helper does not need a
binary search. You have a hypothesis. Test it directly:
git show 8f3a91c
If the diff explains the bug, you are done in ninety seconds instead of eight test cycles.
This is also the moment where commit message quality stops being a matter of taste and
starts being operational. A range of twenty commits called wip, fix, update and
changes tells you nothing, and you have no choice but to bisect. A range where each
subject line says what changed, with a
gitmoji prefix marking the type, is scannable in under a minute.
The payoff for commit discipline arrives months later, in exactly this situation.
#Handing off to bisect
Sometimes reading is not enough. The range is thirty commits, none of them obviously related, and the bug could be anywhere.
That is the right time to bisect, and the triage you just did makes it cheap. Bisecting 200 commits is eight test cycles. Bisecting 30 is five. If a single test cycle involves a build and a manual reproduction, that difference is real time.
git bisect start
git bisect bad HEAD
git bisect good v1.4.0
Better still, if you can express the reproduction as a script, hand the whole thing over:
git bisect run ./scripts/check-eu-tax.sh
The full command set, including skip and the exit code conventions for automated runs,
is in the bisect guide.
#Confirming, then widening
You have a commit. Two things left.
Read the diff in full and satisfy yourself that it explains the observed behaviour. A commit that is merely in the range and looks related is not the same as the cause, and the difference matters because shipping a fix for the wrong commit means the bug comes back.
Then check what else that change touched:
git show --stat 8f3a91c
git blame -L 40,80 src/billing/vat.ts
If a change to a shared helper broke tax rates, it very likely broke something else that nobody has reported yet. The commit that introduced the bug is also the map of everywhere else to look, and that is the part of the investigation that is easy to skip when you are relieved to have found it at all.
#Making blame usable
git blame is the natural next step and it is frequently useless on a repository that has
been reformatted, because every line points at the commit that ran Prettier.
The fix is a file listing the commits to ignore:
# .git-blame-ignore-revs
# Prettier across the codebase
9f2c1a4e8b7d3f6a0c5e2b8d1f4a7c3e6b9d2f5a
# Rename src/lib to src/shared
2b8d1f4a7c3e6b9d2f5a9f2c1a4e8b7d3f6a0c5e
git config blame.ignoreRevsFile .git-blame-ignore-revs
Commit that file to the repository so everyone benefits, and add to it every time you land a formatting-only or rename-only commit. GitHub reads the same file for its blame view, so this fixes it in both places.
Two more flags that change what blame is useful for:
# Follow the line through file moves and copies within the commit.
git blame -C -C src/billing/vat.ts

# Blame the file as it was before a given commit, to see past a rewrite.
git blame <sha>^ -- src/billing/vat.ts
-C -C is what stops blame from attributing an entire file to the commit that moved it,
which on a codebase that has been reorganised is most of them.
#The order that works
Confirm it is a regression. Bracket it with tags or sprint boundaries. Filter by path. Read the remaining commits. Bisect only if reading did not answer it.
Most guides start at the last step, because bisect is the interesting algorithm. In practice the first four steps resolve the majority of regressions in less time than a single bisect cycle takes, and they leave you understanding the change rather than merely knowing its hash.